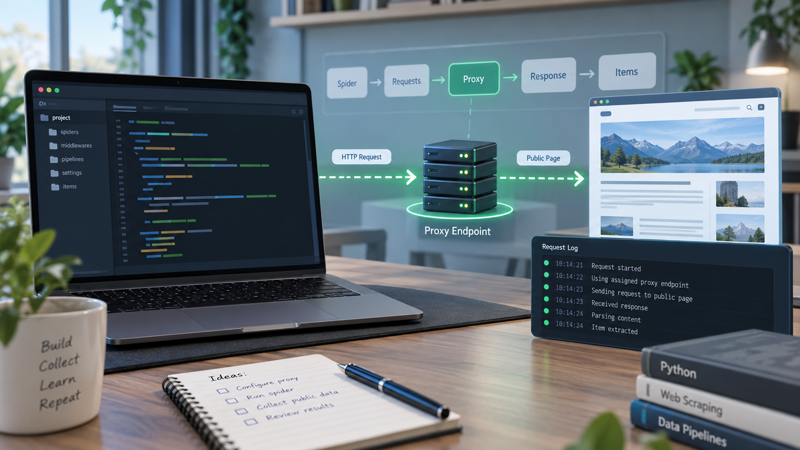
A Scrapy proxy can be applied to one Request through
request.meta["proxy"]
, or supplied more broadly through standard proxy environment variables that HttpProxyMiddleware understands. Start with one authorized public URL and one request-level endpoint. Verify the response and logs before moving the setting to a spider, process, or deployment environment.
Start with the task: know which Scrapy layer owns the proxy
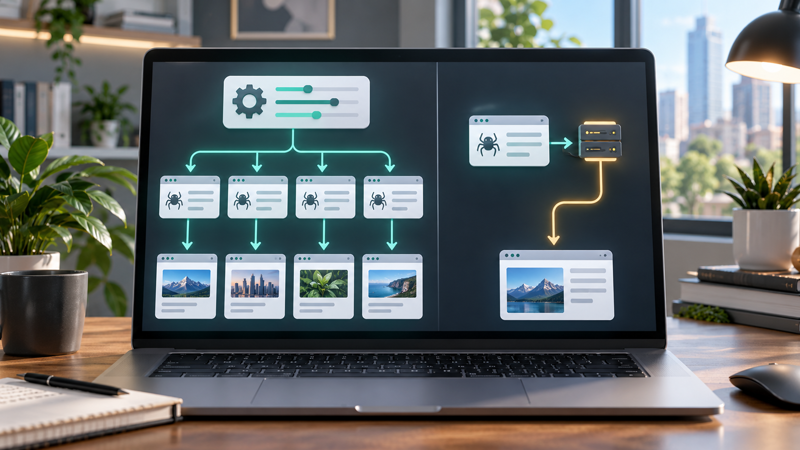
Scrapy's official downloader middleware documentation separates the request object, HttpProxyMiddleware, and download handler. The request carries the optional proxy URL. The middleware reads that value or an applicable environment variable. The download handler performs the connection and may impose protocol limits. Treat these as three separate checkpoints rather than assuming one setting controls everything.
Scope
Configuration point
Best use
One request
request.meta["proxy"]
A controlled test or selected public endpoint
One spider or process
Build Requests with a shared helper
Explicit project logic and logging
Environment
http_proxy
,
https_proxy
,
no_proxy
Deployment-managed defaults
Frequently Asked Questions
Where should a Scrapy proxy be configured for one request?
Set request.meta["proxy"] to the assigned proxy URL for that request. This overrides environment proxy settings for the request.
Can Scrapy read proxy settings from environment variables?
Yes. HttpProxyMiddleware can use http_proxy, https_proxy, and no_proxy environment variables, subject to the selected download handler and project configuration.
How should proxy credentials be stored in a Scrapy project?
Load them from an environment variable or secret manager at runtime. Do not commit usernames, passwords, or complete credential-bearing URLs to source control.
Does every Scrapy download handler support the same proxy features?
Handler capability
DOWNLOAD_HANDLERS
and handler documentation
Confirm protocol compatibility before debugging credentials
Method 1: configure a proxy on one Request
The smallest useful test is a single Request with a fake documentation endpoint replaced at runtime by an assigned value. Keep the target limited to a public page you are authorized to access, set a timeout, and log status, final URL, and a request identifier. Do not begin with high concurrency because it adds retry, throttling, and target behavior to an otherwise simple connection test.
The minimal request can be expressed as five short Python fragments:
. The example hostname is deliberately non-working. Official Scrapy documentation allows a proxy URL with a scheme, host, and port, and it may include credentials. In production, avoid placing credentials directly in the spider or log.
Method 2: choose environment scope deliberately
HttpProxyMiddleware can use
http_proxy
,
https_proxy
, and
no_proxy
. Environment variables are useful when operations owns the deployment configuration and several components need the same approved endpoint. They are less explicit than a request-level setting, so document which process receives them and prevent secrets from appearing in shell history, CI output, crash reports, or container metadata.
A request-level
meta["proxy"]
value overrides the environment proxy for that request. Official documentation also notes that
no_proxy
is ignored when the proxy is specified directly on the request. This matters when a team expects an environment exclusion to protect an internal hostname: request code can bypass that exclusion unintentionally.
Prefer a small helper that constructs Requests and records a redacted endpoint label rather than the complete URL. Review the effective environment at process startup without printing secrets. If the project uses multiple spiders, make the ownership visible in settings documentation instead of duplicating hidden assignments throughout callbacks.
Authentication without committing a secret
Load credentials from a secret manager or protected environment variable. If an assigned URL arrives as separate host, port, username, and password fields, encode the user information safely with a standard URL builder and keep the resulting value in memory only. Avoid string examples containing real customer names, account IDs, tokens, or production hosts.
Scrapy documents a
HTTPPROXY_AUTH_ENCODING
setting, whose default is Latin-1, for proxy authentication encoding. Do not change it as a first response to a 407 status. Confirm the assigned username, password, endpoint, and authentication scheme first, then change encoding only when the provider or network administrator documents that requirement.
Check the download handler before blaming the proxy
Proxy behavior depends on the active download handler. The current official documentation says the built-in HTTP/2 download handler does not support the Request
proxy
meta key. It also documents HTTPS-proxy limitations for one handler and broader HTTP, HTTPS, and SOCKS support for HttpxDownloadHandler. Verify the Scrapy version and handler selected by the project before assuming a proxy scheme should work.
Do not silently switch handlers in a production crawler. A handler change can affect TLS behavior, connection pooling, dependency requirements, and response handling. Reproduce the issue in a minimal project, pin versions, record the original settings, and have the project owner approve the change.
Read failures as evidence: DNS, 407, timeout, or TLS
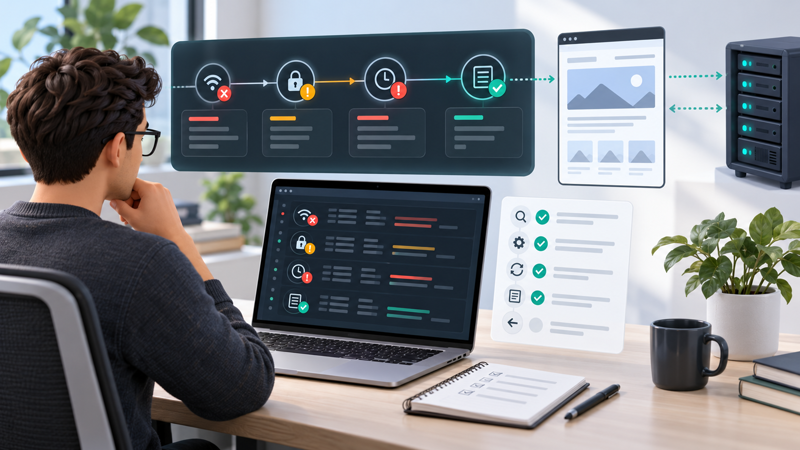
A DNS error may refer to the proxy hostname or the target hostname, depending on the handler and connection path. A 407 response generally points to proxy authentication, but it does not tell you whether the username, password, encoding, or authentication scheme is wrong. A timeout may come from routing, a blocked port, an unavailable endpoint, target delay, or an overly short deadline. A TLS error can occur on either connection leg and should not be fixed by disabling certificate checks.
Capture the exception class, timestamp, Scrapy version, handler, redacted endpoint label, target domain, timeout, retry count, and whether the same test works without the proxy when such a comparison is authorized. Keep response bodies out of logs when they may contain sensitive data. This evidence is much more useful than repeatedly changing credentials and concurrency together.
Quick reference before expanding the crawl
Begin with one Request and one authorized public URL.
Load the assigned endpoint from a protected runtime source.
Choose request-level or environment scope intentionally.
Confirm HttpProxyMiddleware is enabled and identify the download handler.
Log status and exception categories without logging credentials.
Test at low concurrency before adding retries or multiple targets.
Respect authorization, robots guidance, site terms, and rate limits.
Restore the original settings when the test is complete.
Use the proxy server setup guide for assigned fields and the proxy settings field reference before changing project code. For exact middleware and handler behavior, follow the Scrapy downloader middleware documentation for the version you run. IPIPD currently confirms static IP and VPS as product categories; this article does not infer a network classification, claim that VPS is a proxy type, or promise crawler access, performance, acceptance, or business results.
No. Official documentation notes handler-specific limits, including no proxy support for the built-in HTTP/2 handler and differing SOCKS or HTTPS-proxy support.